Exhibit 8.4
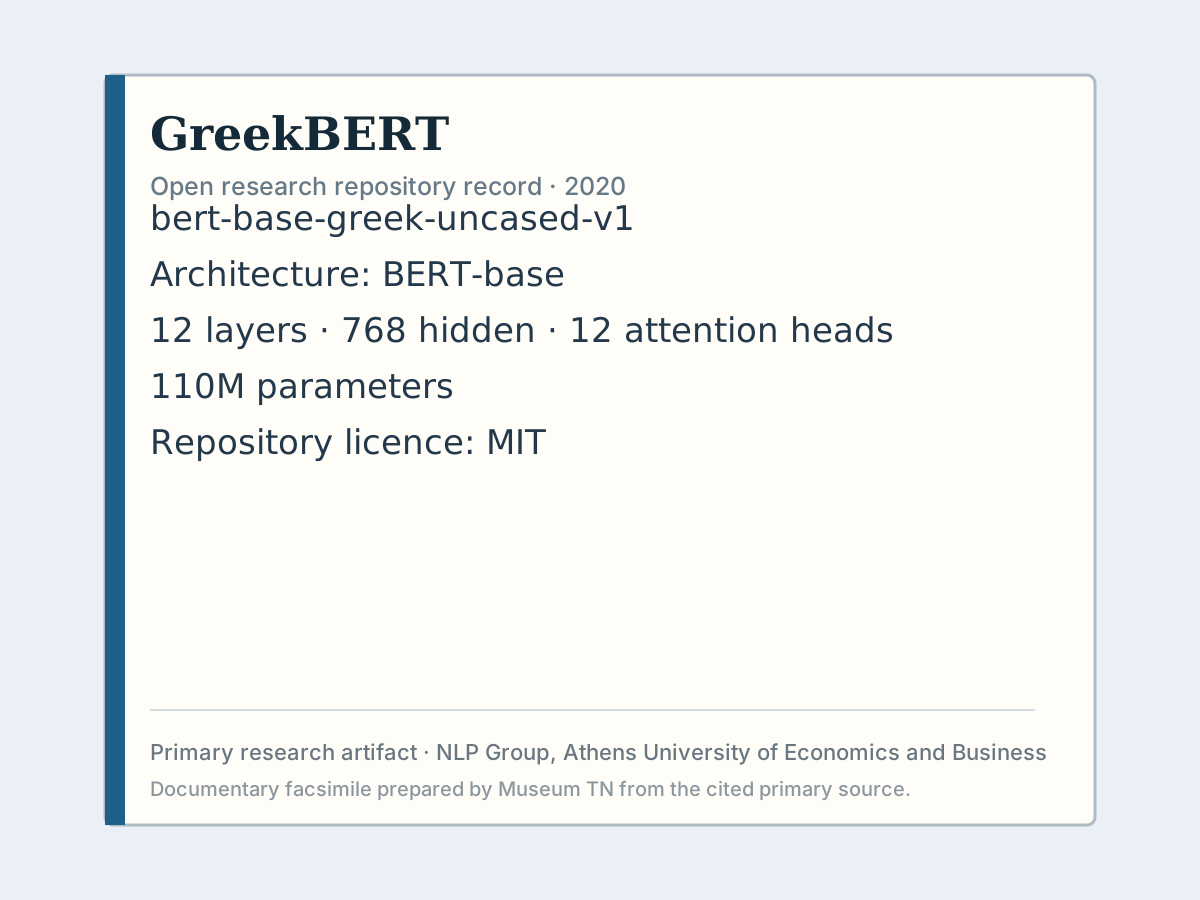
2020GreekBERT
Researchers release a BERT model trained specifically on Greek text, showing why a language with far fewer digital resources than English benefits from dedicated models and evaluation.
Why it is in the museum
Modern Greek AI runs from language technology and research to open Greek models and national computing infrastructure.
Evidence for this exhibit
Institutional / scientific source
This source supports the dated event and the core claim described in this exhibit.
Main source: Koutsikakis et al. (2020), GreekBERT.
What to keep in mind: The evidence is used only for the claim stated on this page; broader interpretations remain curatorial.
Ask the exhibit
This small guide uses only the documented facts on this page. If your question goes beyond them, it will say so instead of filling the gap.
Start with one of the questions above.