Exhibit 5.2
2013Words become numbers
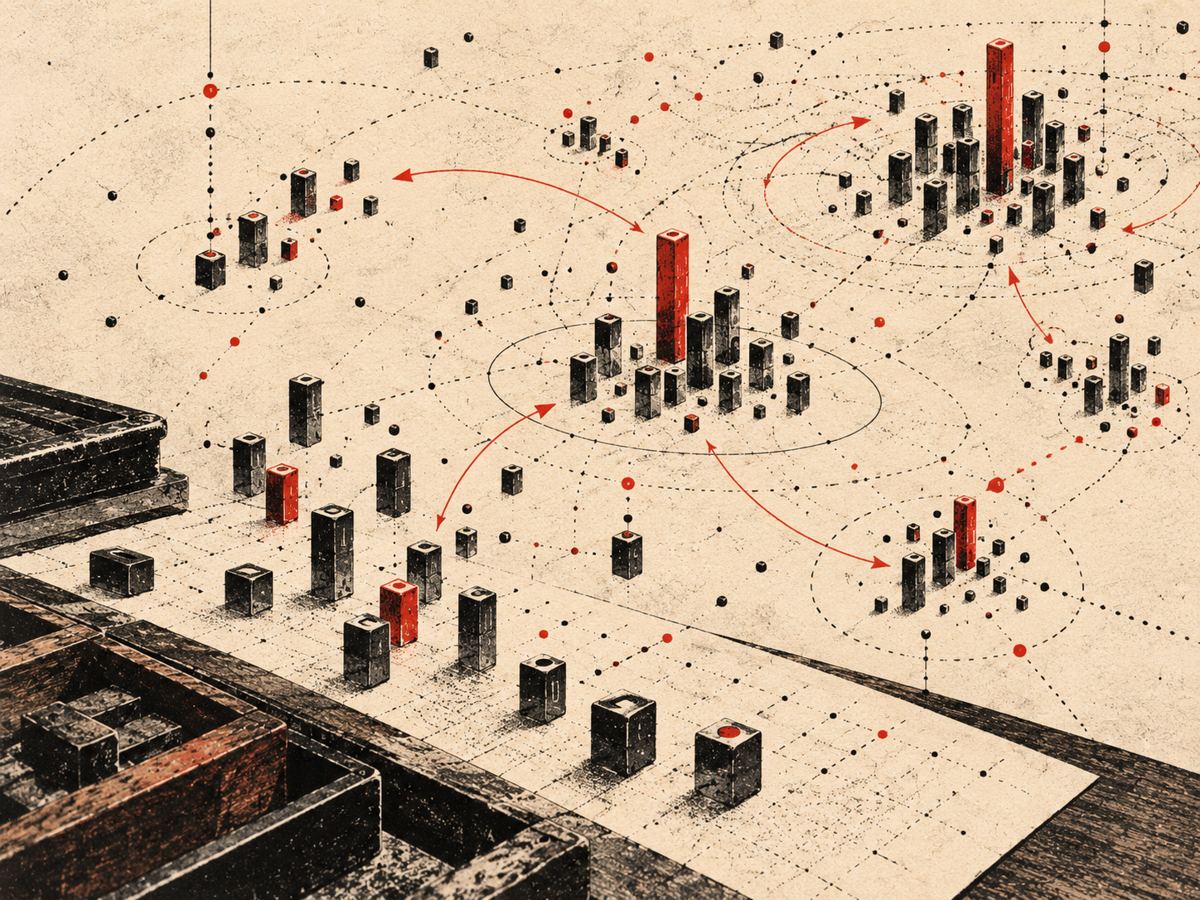
With word2vec, each word can be represented as a point in a numerical space. Words used in similar contexts tend to end up close together.
Why it is in the museum
Language is treated as a prediction problem. From Shannon’s statistical sequences, the story leads to Transformers and large language models.
What supports this exhibit
Primary research paper
Learning dense vector representations of words from large text corpora.
Main source: Mikolov, T. et al. (2013), “Efficient Estimation of Word Representations in Vector Space”.
What to keep in mind: Primary source.
Ask the exhibit
This small guide uses only the information documented on this exhibit page. If your question goes beyond that evidence, it will say so instead of inventing an answer.
Start with one of the suggested questions above, or type your own.